
RAYA 2026 – Embodied AI in Academic and Industrial Research
- Post author:Jan Hübner
- Post published:October 13, 2026
- Post category:Article / Events / Future Robotics / RAYA / Review
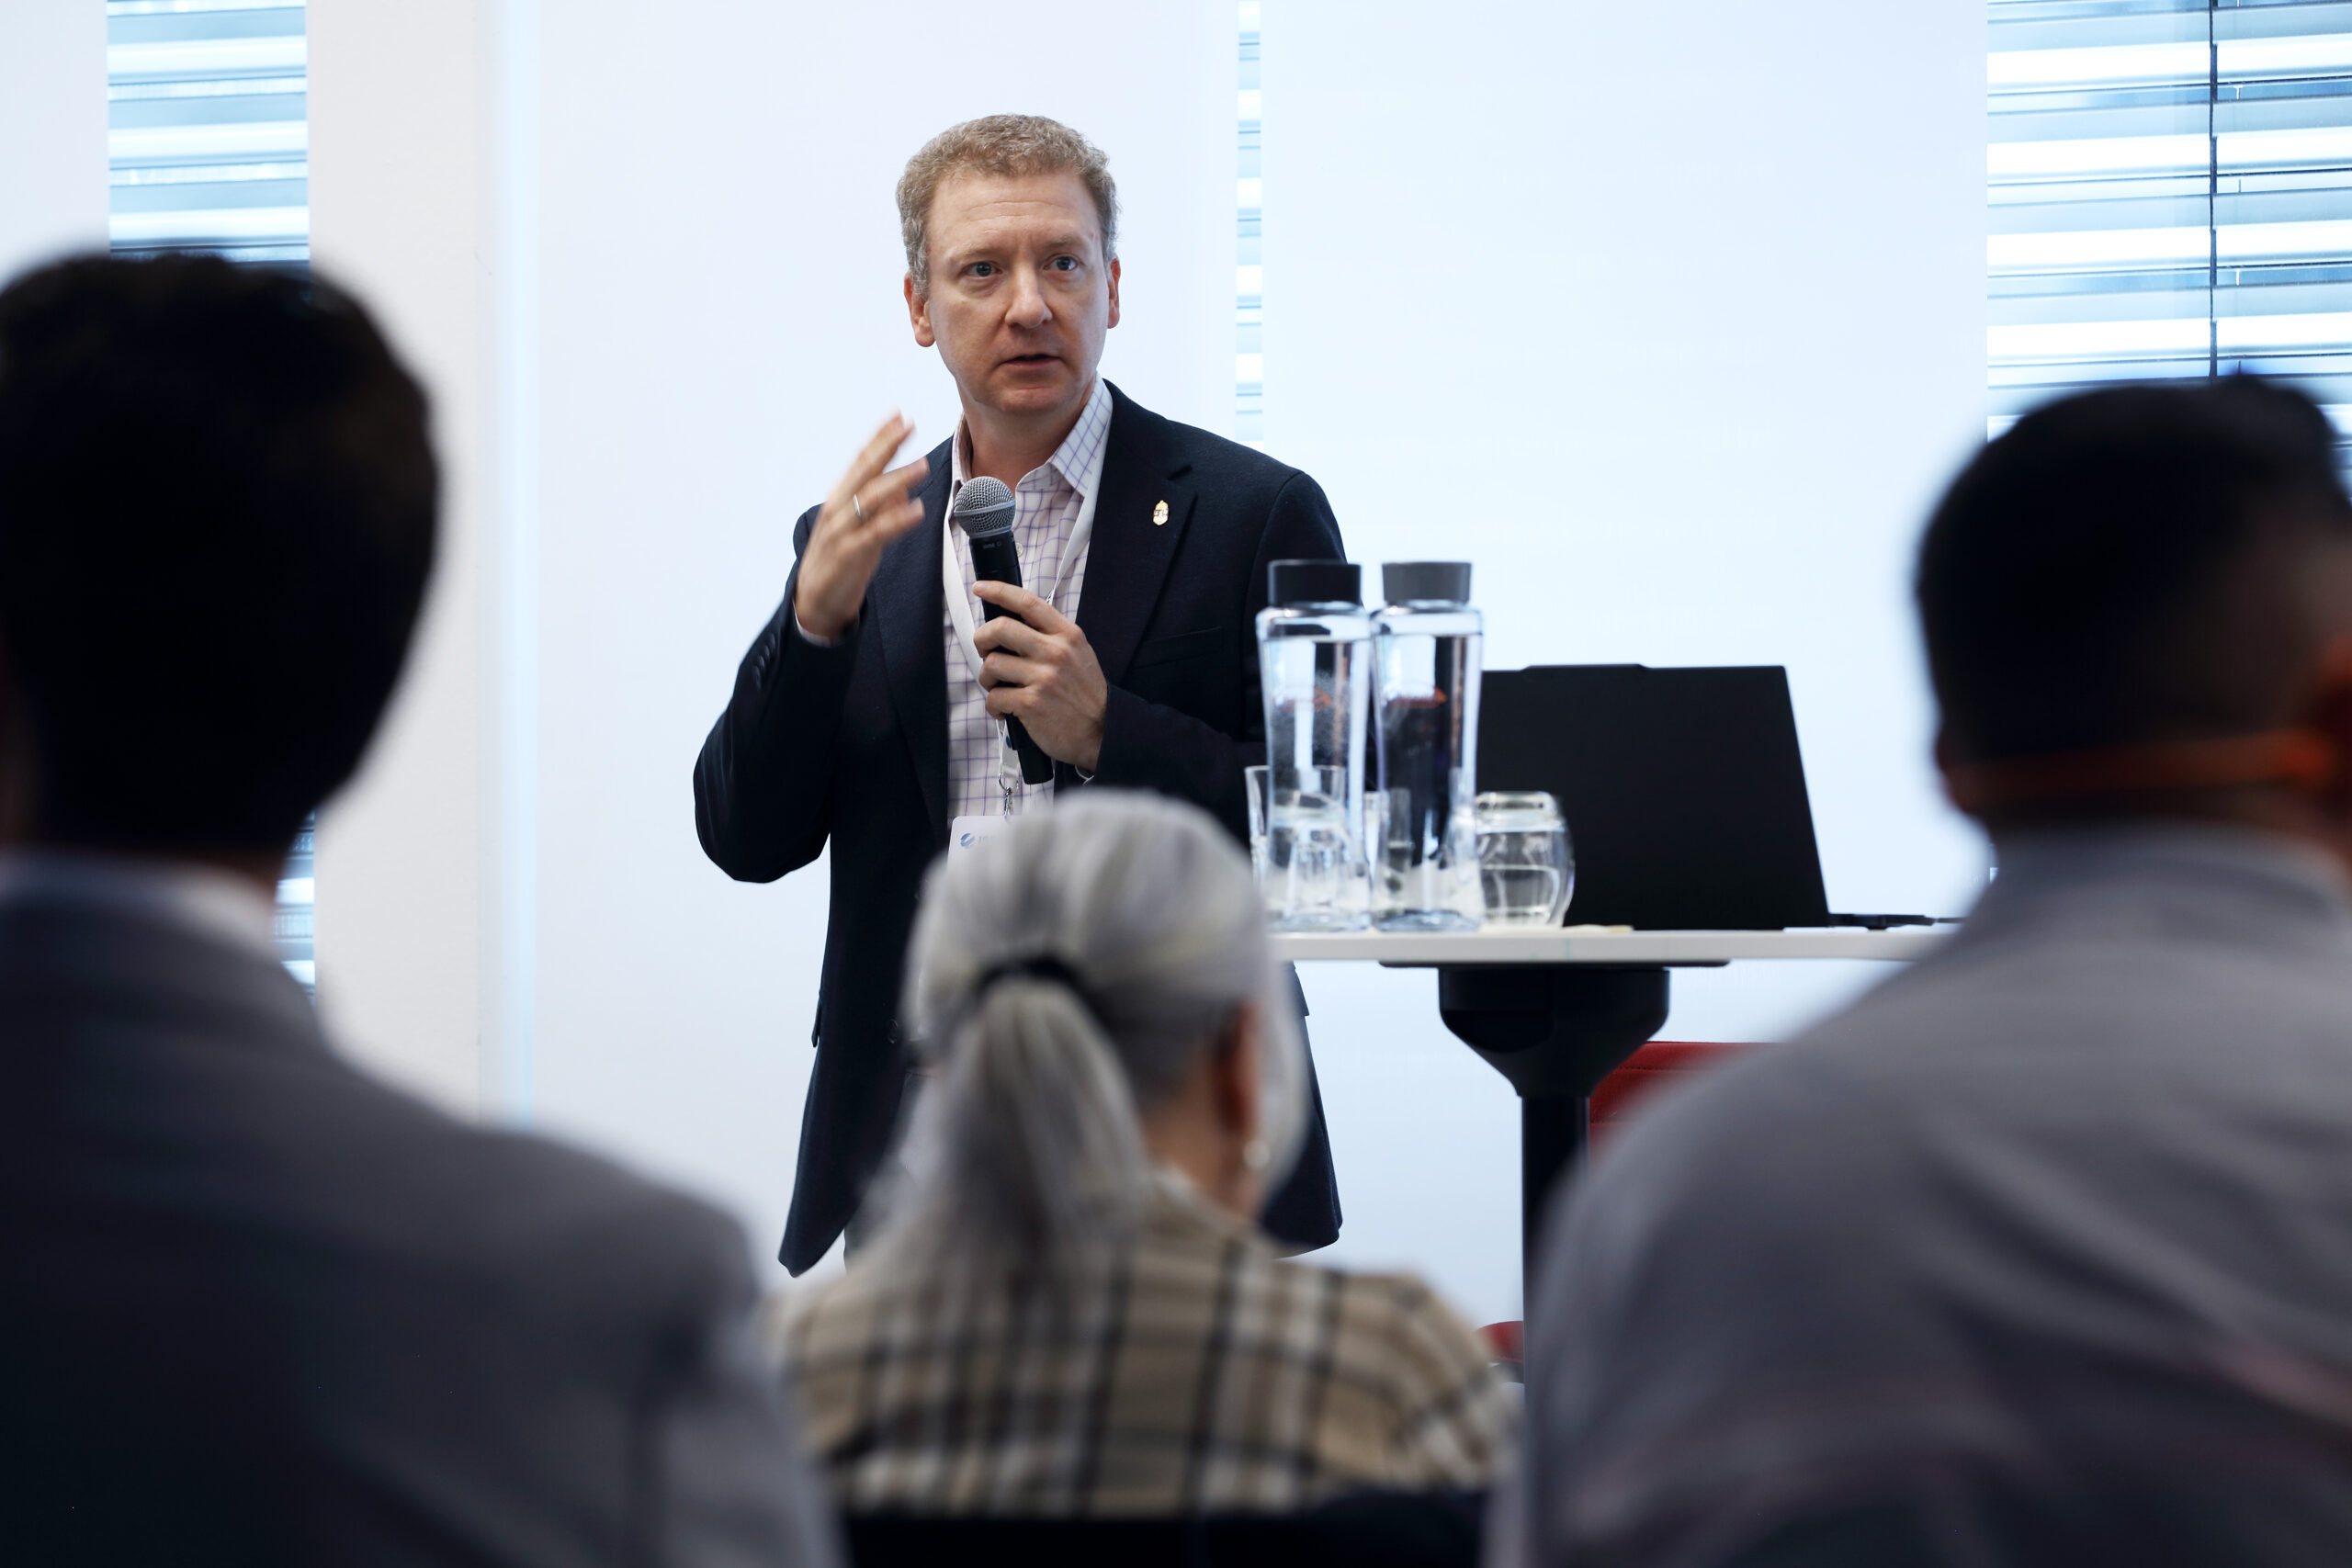
How far have robots and AI come, and what are the current challenges in merging the two? Where are the industrial expectations for AI-driven robotics, and where does academia stand in this picture? Prof. Dr. Péter Galambos from Obuda University explored these questions on the first day of the ISPE Robotics & AI and RAYA event at Takeda, giving deeper insight into how far we’ve come and where we are moving.
More than a century has passed since Karel Čapek introduced the term “robot” in his play R.U.R., and several decades have elapsed since Antal Bejczy contributed foundational work to modern robotics. Nevertheless, substantial disparity persists between artificial intelligence capabilities in digital environments and those in the physical domain. While AlexNet initiated a deep learning paradigm shift in 2012 and large language models redefined natural language processing in 2022, embodied AI remains constrained by Moravec’s paradox. Current algorithms demonstrate proficiency in synthesizing complex software architecture yet encounter fundamental difficulties when performing basic physical manipulation tasks. Interaction with the physical world requires processing high-dimensional, continuous sensory streams, representing a problem space fundamentally more complex than digital data manipulation.
In the analysis of learning paradigms and data constraints, physical agent instruction relies primarily on Reinforcement Learning (RL) and Imitation Learning (IL). Reinforcement learning operates through goal-directed trial and error within specified reward function parameters; however, the precise formulation of effective reward structures remains challenging. Conversely, imitation learning derives control policies directly from human expert demonstrations. Although imitation learning offers increased algorithmic stability, it exhibits limited generalization under environmental distribution shifts and remains bounded by the performance boundaries of the demonstration dataset. Both approaches encounter critical data scarcity constraints. Physical grounding cannot be acquired through web-scale text scraping in the manner of large language model pre-training. Current industry methodologies attempt to mitigate this bottleneck through physics-based simulation environments, egocentric video corpus utilization, high-cost human teleoperation data collection, and large-scale World Model architectures.
In parallel with data acquisition challenges, model architectures and task orchestration frameworks are undergoing rapid evolution. Early emphasis on Vision-Language-Action (VLA) architectures has increasingly transitioned toward World Action Models designed for concurrent prediction of future video frames and action vectors. This development is evidenced by platforms such as Nvidia Cosmos 3, alongside research frameworks including DreamZero and Mimic. However, embodied AI currently lacks the standardized task orchestration systems present in software-centric AI architectures. While large language models leverage structured protocols such as the Model Context Protocol to execute tool-use workflows, robotic control architectures lack equivalent operational standardization. Structuring robotic control hierarchies through centralized orchestrators that delegate discrete sub-tasks (such as perception or grasping) to domain-specific modules presents a viable alternative to monolithic model configurations.
Regarding real-world operational deployment, system failure rates and haptic feedback limitations present substantial engineering barriers. Despite public demonstrations of humanoid capabilities, robotic systems remain insufficiently robust for industrial deployment, while rigorous empirical evaluation of failure modes remains underreported. Physical task execution is subject to compounding error probabilities; a ten-step operational sequence with a 95% individual step success rate yields an overall task completion probability of approximately 60%. A primary contributing factor is the predominant reliance on optical vision systems. Relying exclusively on computer vision for contact-rich tasks is analogous to manual operation under sensory deprivation. While visual inputs provide spatial localization data, tactile and force sensing are required for stable physical interaction. Models integrating force feedback exhibit superior performance in contact-rich environments, yet tactile training datasets remain extremely scarce relative to visual data formats.
This domain of reality highlights the imperative synergy across the academic-industrial divide. By mid-2026, venture capital allocations to robotics enterprises reached $18.8 billion, affording commercial entities access to proprietary datasets comprising hundreds of thousands of physical operational hours. Academic research institutions cannot match this capital scale. Consequently, academic efforts should focus on fundamental research challenges overlooked by commercial investment, including standardized evaluation frameworks, tactile sensor integration, formal safety guarantees, and open-source modular toolkits.